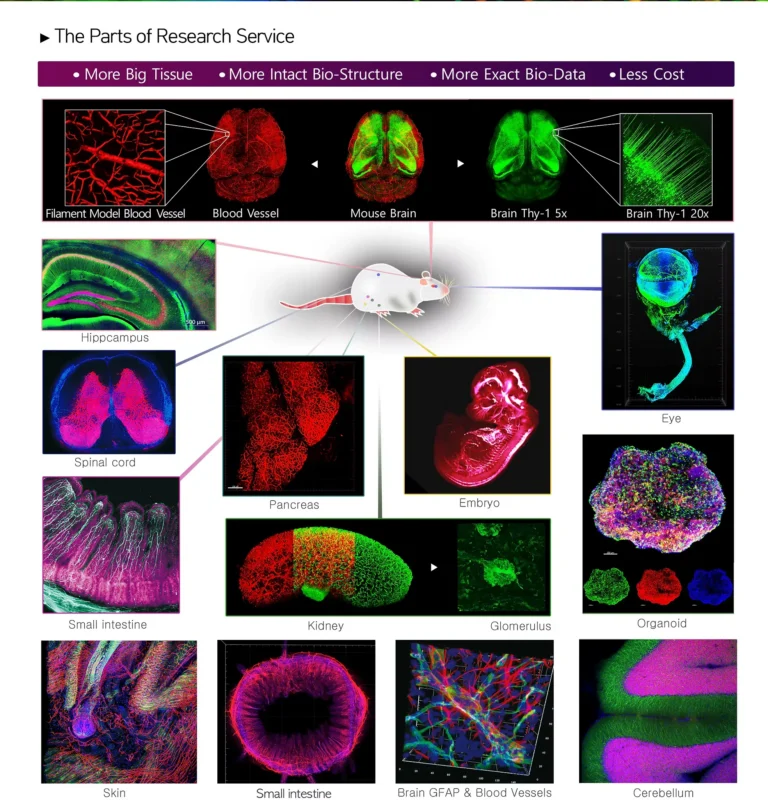
Meet the Binaree Product Line: Which Tissue Clearing System Is Right for Your Lab?
“Tissue clearing” isn’t one product — it’s a small ecosystem of reagents and, in Binaree’s case, an optional automated system built around it. Choosing the

Designing a rigorous behavioral experiment is only half the challenge. Making it run reliably, trial after trial, session after session, is where most labs lose time. Maestro was built to solve exactly that problem, giving researchers a single environment to connect devices, define protocol logic, and capture clean, reproducible data automatically.
Behavioral neuroscience relies on precise coordination between sensory stimulation, response detection, and motivation. Protocols investigating attention (1), working memory (2), and decision-making (3) all depend on the same underlying requirement: presenting a stimulus, measuring a response, and reinforcing behavior through reward, punishment, or avoidance, all in careful synchrony.
A typical setup pulls together sensory stimulation devices such as auditory, visual, or tactile stimulators, reward-delivery systems such as water or food-pellet dispensers, and response devices such as levers, decision wheels, or lick detectors. Coordinating all of it usually means custom-built software, and custom software means ongoing investment in development, validation, and maintenance just to keep an experiment running the way it was designed.

Open-source platforms, including the widely adopted decision-making protocol from the International Brain Laboratory, have made behavioral neuroscience more standardized and accessible. But many of these solutions are built around one specific paradigm or hardware configuration. Adapting them to a new task often means reworking both the software and the rig, which slows labs down right when they want to move fast.
Maestro takes a different approach. Instead of locking researchers into a predefined protocol, it provides a flexible environment for configuring experimental sequences and device interactions on their own terms. One platform, any behavioral design.
To show what that looks like in practice, this post walks through how Maestro was used to build and run a complex decision-making task in mice.
Modeled on the International Brain Laboratory’s decision-making paradigm (3) and recent findings from Gong et al. (4), the task head-fixes a mouse in front of a screen. An auditory cue, a 5 kHz pure tone, signals that a Gabor patch is about to appear on the left or right side of the screen. The mouse turns a wheel to steer the patch toward the center.
Get it right, and the mouse earns a 10% sucrose reward: a Hit. Turn the wheel the wrong way, and the patch drifts to the edge: a Miss. No response within 60 seconds triggers white noise and a brief air puff to the vibrissae. A quiet period before the patch appears keeps the wheel still and the trial clean.
To keep the data meaningful, Maestro randomizes which side the patch appears on, correcting for side bias when it emerges, and varies the inter-trial interval so the animal can’t anticipate the next stimulus. Reward volume shifts too. Every fifth Hit, for example, delivers a larger dose of sucrose solution (4), adding another layer of behavioral richness without adding another layer of manual control.
The session wraps automatically after 60 minutes, or sooner if the mouse stops licking delivered rewards within 90 seconds.
This is where Maestro does the heavy lifting. It drives and synchronizes every device in the rig while simultaneously managing randomization, timing, and session-end logic in the background:
At session start, Maestro fires up both camera recordings, blanks the screen, and starts the clock. From there, it cycles through trial blocks: a quiet period, stimulus presentation, and response classification as Hit, Miss, or No Response, continuing until the session timer or the reward-timeout condition ends it.

Every connected device hands Maestro a set of variables, actions, and events. Maestro weaves these together with its own variables, equations, rules, timers, and state machine to build the full behavioral workflow, no custom code required.

Variables track responses and stimulus parameters like Gabor patch position and contrast. Equations handle randomization. Rules govern reward volume. Timers manage session length and event timing down to the response window. The state machine ties it all together, sequencing task phases, defining transition conditions, and triggering actions at each step, so the entire protocol runs as one coordinated system instead of a patchwork of manual triggers.
Great behavioral science depends on tight coordination between stimulation, response detection, reward delivery, and data capture. Building that coordination from scratch is expensive, and keeping it validated and maintained over time is even more so.
Maestro removes that overhead. It hands researchers a shared control environment for behavioral devices while leaving full ownership of the experimental design in their hands. The task in this example, device configurations, trial phases, randomized parameters, conditional logic, synchronized actions, and recorded events, all came together in a single platform.
No fixed paradigm, no rigid hardware assumptions. Just the building blocks to configure, modify, document, and reproduce behavioral workflows on a lab’s own terms.
Ready to see what Maestro can do with your setup? Request a demo.


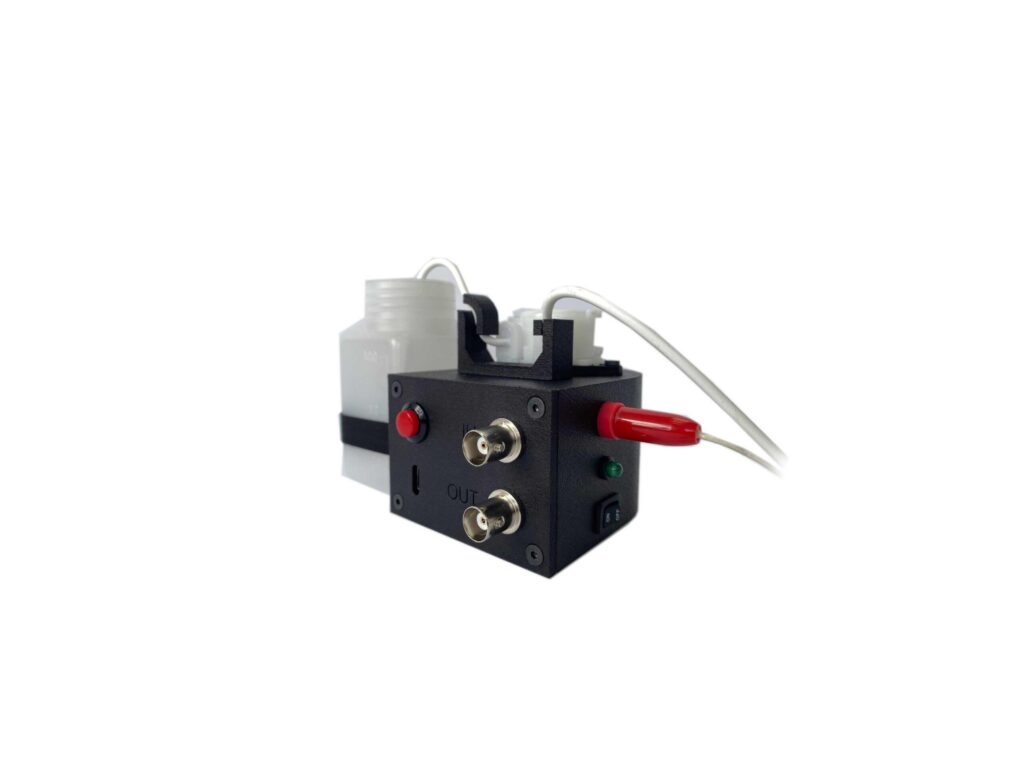
“Tissue clearing” isn’t one product — it’s a small ecosystem of reagents and, in Binaree’s case, an optional automated system built around it. Choosing the
Designing a rigorous behavioral experiment is only half the challenge. Making it run reliably, trial after trial, session after session, is where most labs lose